

TacVerse · XTac-UMI-G1 Head-view
Collection
Bimanual visuo-tactile demos with XTac-UMI-G1 grippers and Pico headset stereo cameras. LeRobot v3.0 format. • 14 items • Updated • 1

Representative frames from TacVerse's bimanual demonstrations.
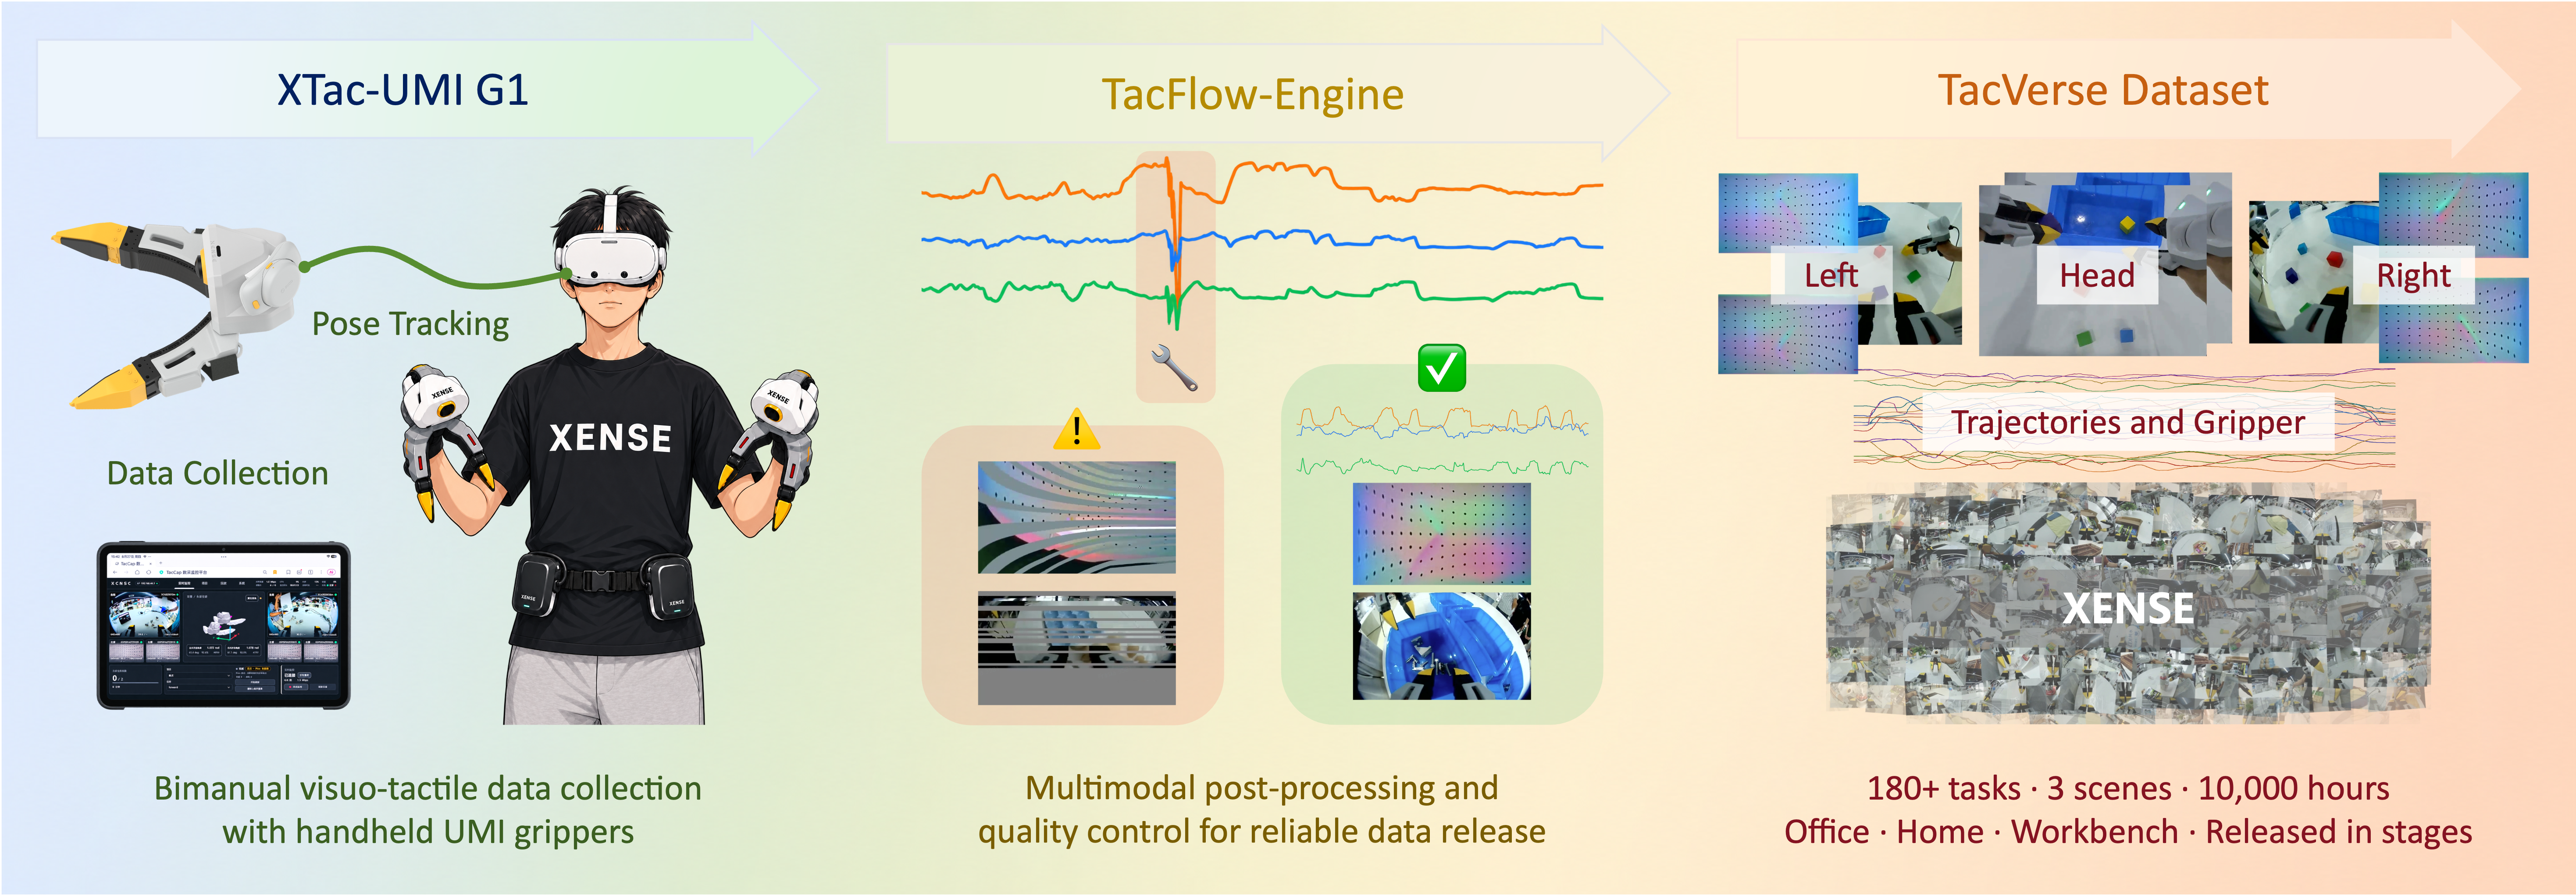
Collected with XTac-UMI-G1 grippers, released as LeRobot datasets.
This dataset was created using LeRobot.
This dataset is public. Download it and load it with LeRobot:
hf download TacVerse/xtac-umi-g1-remove-oring-a --repo-type dataset --local-dir ./xtac-umi-g1-remove-oring-a
from lerobot.datasets.lerobot_dataset import LeRobotDataset
ds = LeRobotDataset("TacVerse/xtac-umi-g1-remove-oring-a", root="./xtac-umi-g1-remove-oring-a")
Faces of people appearing in the camera streams (wrist and head cameras) have been anonymized: they were detected automatically and pixelated before release. The tactile streams contain no people and are unchanged. Automatic detection can miss a face; if you find one that is not masked, please contact us via the TacVerse landing page and we will fix it.
Every episode carries automatic language annotations produced by a vision-language model from the head-camera
and tactile frames. They are model-generated descriptions, not human labels; spot-check them before relying on them.
The frame data and meta/info.json are unchanged, so the dataset loads the same way with any LeRobot version.
meta/language_persistent.parquet — one row per language atom, using the row schema of LeRobot's
language_persistent column (role, content, style, timestamp, camera, tool_calls) plus episode_index.
style="task_aug" is a one-sentence summary of what the episode actually shows; style="subtask" rows are the
step-by-step segmentation. A subtask becomes active at its timestamp (seconds from episode start) and stays
active until the next subtask row, so exactly one subtask is active at any frame. Steps done by one gripper are
marked (left arm) / (right arm); steps the two grippers start together are joined as left: …; right: ….meta/annotations.parquet — one row per episode with the full annotation as JSON (labels_json): scene objects,
the raw timeline (per gripper, with object / destination / progress), key events, state changes, a scene graph
and a completion judgement, plus the instruction the model was given (annotated_instruction) and the model.Active subtask for each frame:
import pandas as pd
from lerobot.datasets.lerobot_dataset import LeRobotDataset

root = "./xtac-umi-g1-remove-oring-a"
ds = LeRobotDataset("TacVerse/xtac-umi-g1-remove-oring-a", root=root)
lang = pd.read_parquet(f"{root}/meta/language_persistent.parquet")
sub = lang[lang["style"] == "subtask"].sort_values(["episode_index", "timestamp"])

def subtask_at(episode_index: int, t: float) -> str:
    rows = sub[(sub.episode_index == episode_index) & (sub.timestamp <= t + 1e-6)]
    return rows.iloc[-1]["content"]

frame = ds[0]
print(subtask_at(int(frame["episode_index"]), float(frame["timestamp"])))
{
    "codebase_version": "v3.0",
    "robot_type": "xtac_umi_g1",
    "collection_stack": "xense-taccap-lerobot",
    "total_episodes": 896,
    "total_frames": 1729574,
    "total_tasks": 1,
    "chunks_size": 1000,
    "data_files_size_in_mb": 100,
    "video_files_size_in_mb": 200,
    "fps": 30,
    "splits": {
        "train": "0:896"
    },
    "data_path": "data/chunk-{chunk_index:03d}/file-{file_index:03d}.parquet",
    "video_path": "videos/{video_key}/chunk-{chunk_index:03d}/file-{file_index:03d}.mp4",
    "features": {
        "action": {
            "dtype": "float32",
            "names": [
                "left_tcp.x",
                "left_tcp.y",
                "left_tcp.z",
                "left_tcp.r1",
                "left_tcp.r2",
                "left_tcp.r3",
                "left_tcp.r4",
                "left_tcp.r5",
                "left_tcp.r6",
                "left_gripper.pos",
                "right_tcp.x",
                "right_tcp.y",
                "right_tcp.z",
                "right_tcp.r1",
                "right_tcp.r2",
                "right_tcp.r3",
                "right_tcp.r4",
                "right_tcp.r5",
                "right_tcp.r6",
                "right_gripper.pos",
                "head.x",
                "head.y",
                "head.z",
                "head.r1",
                "head.r2",
                "head.r3",
                "head.r4",
                "head.r5",
                "head.r6"
            ],
            "shape": [
                29
            ]
        },
        "observation.state": {
            "dtype": "float32",
            "names": [
                "left_tcp.x",
                "left_tcp.y",
                "left_tcp.z",
                "left_tcp.r1",
                "left_tcp.r2",
                "left_tcp.r3",
                "left_tcp.r4",
                "left_tcp.r5",
                "left_tcp.r6",
                "left_gripper.pos",
                "right_tcp.x",
                "right_tcp.y",
                "right_tcp.z",
                "right_tcp.r1",
                "right_tcp.r2",
                "right_tcp.r3",
                "right_tcp.r4",
                "right_tcp.r5",
                "right_tcp.r6",
                "right_gripper.pos",
                "head.x",
                "head.y",
                "head.z",
                "head.r1",
                "head.r2",
                "head.r3",
                "head.r4",
                "head.r5",
                "head.r6"
            ],
            "shape": [
                29
            ]
        },
        "observation.images.left_tactile_left": {
            "dtype": "video",
            "shape": [
                400,
                700,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 400,
                "video.width": 700,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.left_tactile_right": {
            "dtype": "video",
            "shape": [
                400,
                700,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 400,
                "video.width": 700,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.left_wrist": {
            "dtype": "video",
            "shape": [
                480,
                640,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 480,
                "video.width": 640,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.right_tactile_left": {
            "dtype": "video",
            "shape": [
                400,
                700,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 400,
                "video.width": 700,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.right_tactile_right": {
            "dtype": "video",
            "shape": [
                400,
                700,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 400,
                "video.width": 700,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.right_wrist": {
            "dtype": "video",
            "shape": [
                480,
                640,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 480,
                "video.width": 640,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.head_left": {
            "dtype": "video",
            "shape": [
                480,
                640,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 480,
                "video.width": 640,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "observation.images.head_right": {
            "dtype": "video",
            "shape": [
                480,
                640,
                3
            ],
            "names": [
                "height",
                "width",
                "channels"
            ],
            "info": {
                "video.height": 480,
                "video.width": 640,
                "video.codec": "h264",
                "video.pix_fmt": "yuv420p",
                "video.is_depth_map": false,
                "video.fps": 30,
                "video.channels": 3,
                "has_audio": false
            }
        },
        "timestamp": {
            "dtype": "float32",
            "shape": [
                1
            ],
            "names": null
        },
        "frame_index": {
            "dtype": "int64",
            "shape": [
                1
            ],
            "names": null
        },
        "episode_index": {
            "dtype": "int64",
            "shape": [
                1
            ],
            "names": null
        },
        "index": {
            "dtype": "int64",
            "shape": [
                1
            ],
            "names": null
        },
        "task_index": {
            "dtype": "int64",
            "shape": [
                1
            ],
            "names": null
        },
        "observation.tracker_confidence": {
            "dtype": "float32",
            "names": [
                "left_tracker.confidence",
                "right_tracker.confidence"
            ],
            "shape": [
                2
            ]
        }
    },
    "tacflow_stage": "postprocess.anonymize",
    "tcp_frame_convention": "mirrored-v1"
}
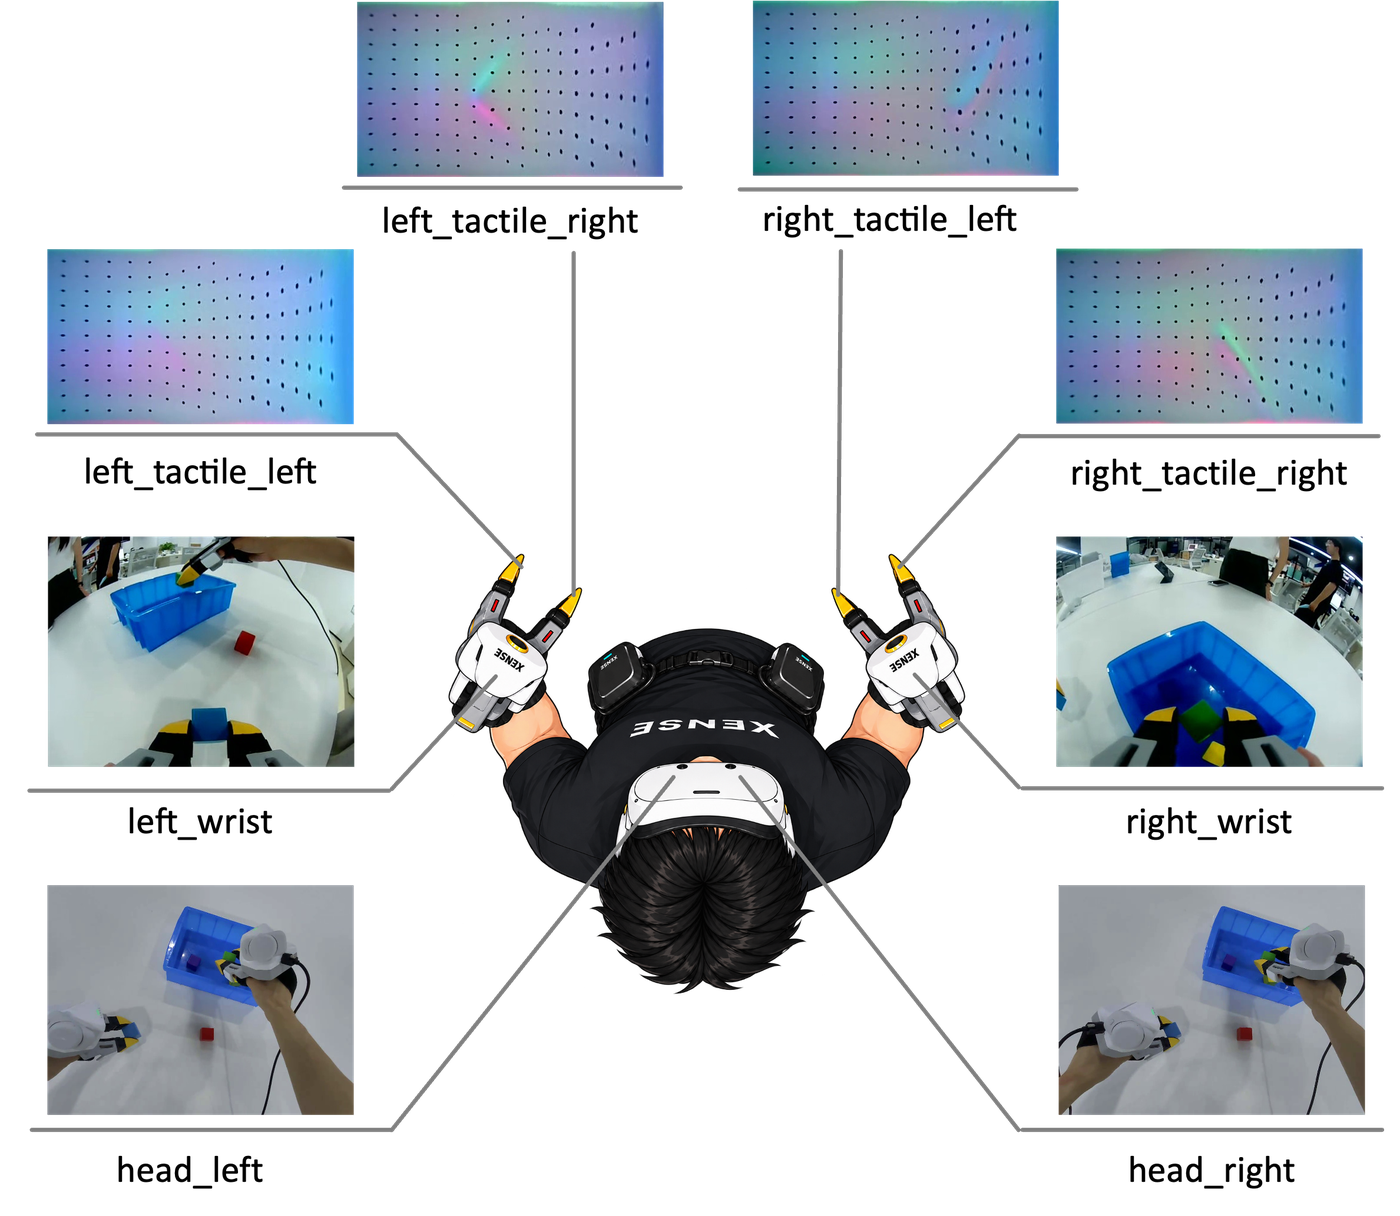
Tactile keys map to fingertip sensors; wrist keys to gripper cameras; head keys to the headset's stereo eyes.
BibTeX:
@misc{tacverse2026,
  title        = {TacVerse: A Large-Scale Bimanual Visuo-Tactile Manipulation Dataset},
  author       = {Xense Robotics},
  year         = {2026},
  howpublished = {\url{https://huggingface.co/datasets/TacVerse/TacVerse}},
  note         = {Collected with the XTac-UMI-G1 handheld gripper and Xense Neutron visuotactile sensors}
}